Wafer-Scale and Multi-GPU Systems for AI
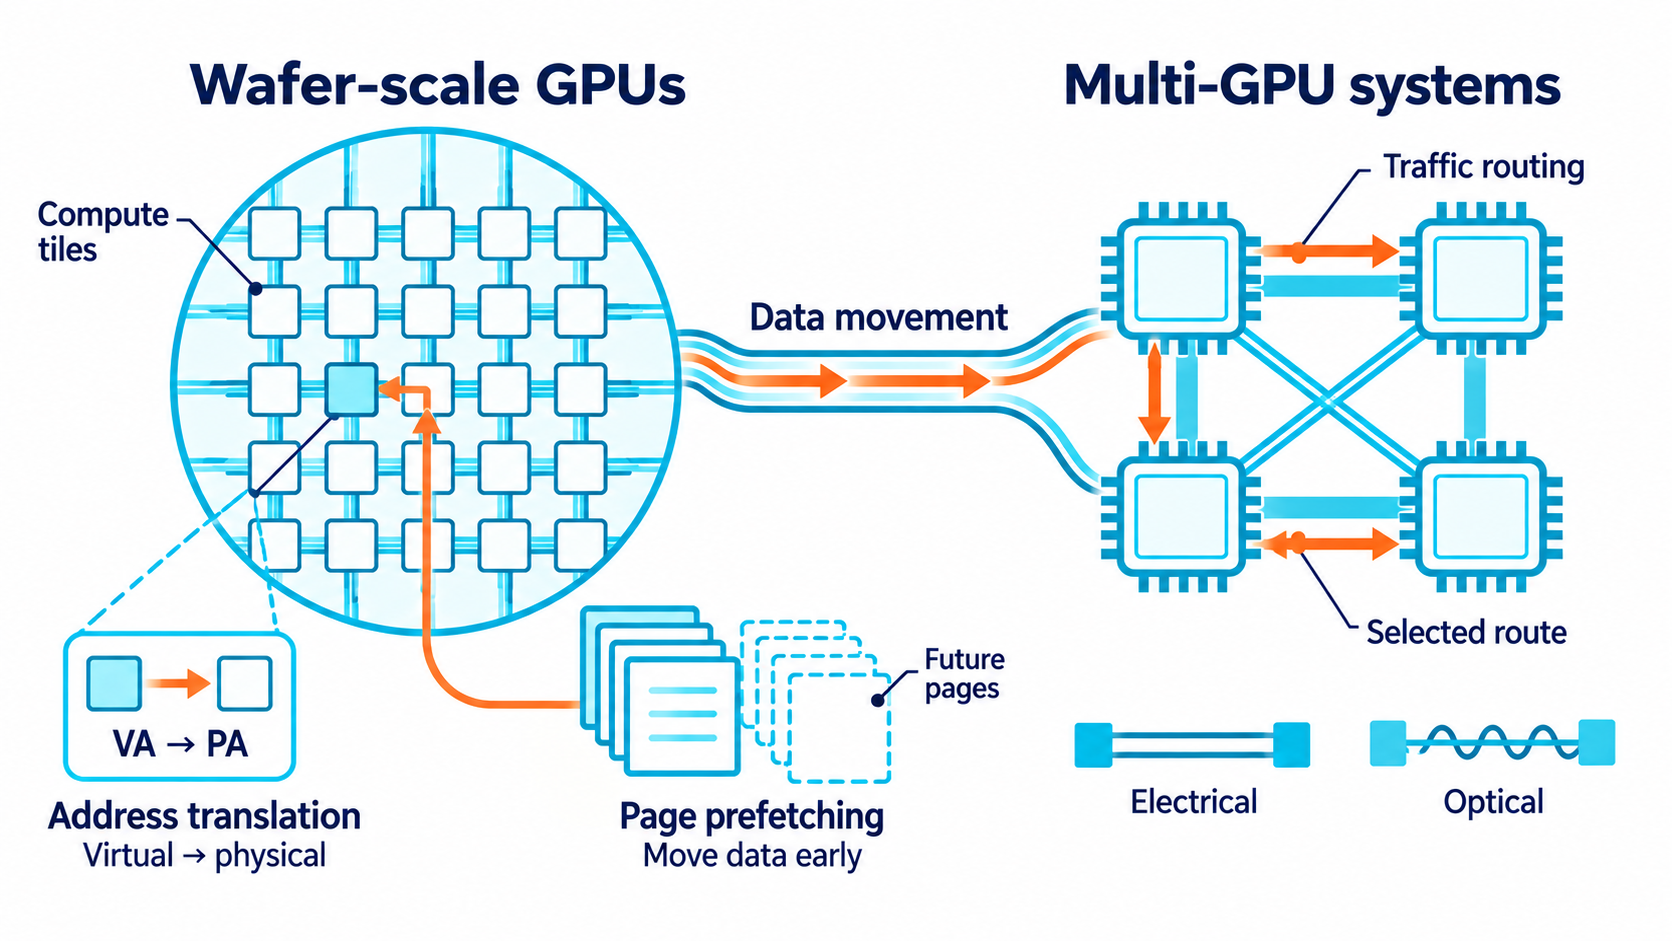
Data moves among compute tiles in wafer-scale GPUs and devices in multi-GPU systems. Address translation maps virtual to physical addresses, page prefetching anticipates data movement, and traffic routing uses different network paths. Electrical and optical links connect compute units.

Research questions

  • How should address translation work across a wafer-scale GPU?
  • How can page prefetching and memory techniques reduce the cost of data movement?
  • How should network traffic use interconnects with non-uniform bandwidth?
  • How do electrical and optical interconnect choices affect wafer-scale and multi-GPU systems?

Publications

2026

GPGPU 2026
RIPPLE: Ring-based Page Prefetching and Layered Translation for Wafer-Scale GPUs
Daoxuan Xu, Ying Li, Jie Ren, Yifan Sun
HPCA 2026
HDPAT: Hierarchical Distributed Page Address Translation for Wafer-Scale GPUs
Daoxuan Xu, Ying Li, Yuwei Sun, Jie Ren, Yifan Sun

2025

ISCA 2025
NetCrafter: Tailoring Network Traffic for Non-Uniform Bandwidth Multi-GPU Systems
Amel Fatima, Yang Yang, Yifan Sun, Rachata Ausavarungnirun, Adwait Jog
GPGPU 2025
Exploring the Wafer-Scale GPUs
Daoxuan Xu, Le Xu, Jie Ren, Yifan Sun

2022

GPGPU 2022
Understanding Wafer-Scale GPU Performance using an Architectural Simulator
Chris Thames, Hang Yan, Yifan Sun

GPU Architecture

2026

HPCA 2026
QuCo: Efficient and Flexible Hardware-Driven Automatic Configuration of Tile Transfers in GPUs
Nicolas Meseguer, Daoxuan Xu, Yifan Sun, Michael Pellauer, José L. Abellán, Manuel E. Acacio

2025

ISCA 2025
The Sparsity-Aware LazyGPU Architecture
Changxi Liu, Miao Yu, Yifan Sun, Trevor E. Carlson
GPGPU 2025
ACTA: Automatic Configuration of the Tensor Memory Accelerator for High-End GPUs.
Nicolás Meseguer, Yifan Sun, Michael Pellauer, José L. Abellán, Manuel E. Acacio